
Are Your Advertisers Showing Up in AI Answers?

Somewhere this week, a buyer in one of your advertiser’s categories opened an AI assistant and asked which company they should go with.
They got an answer. A few names came back, described in a paragraph or two, with the sort of confidence a person uses when they have already made up their mind. The buyer read it, formed an impression, and moved on.
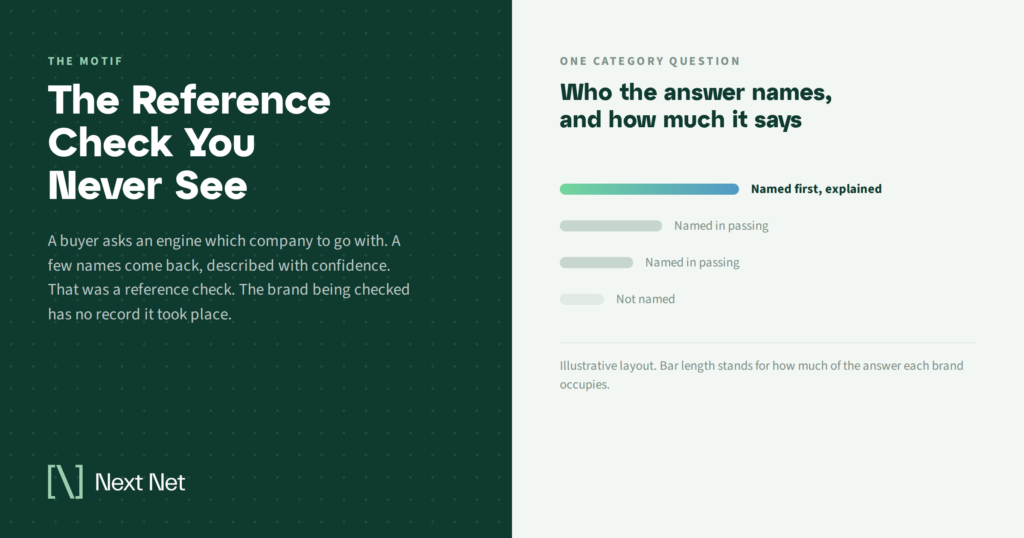
That was a reference check. Nobody requested it, nobody saw it happen, and the brand being checked has no record that it took place.
Your advertisers are being referenced this way every day, in your category, on questions you cover better than anyone. You can find out what those references say. That is a conversation almost no one is having with them yet.
It is also, for a publisher, an unusually comfortable conversation to be in. Most of what the sales team has carried into advertiser meetings for the last two years has been an explanation of something getting smaller. This one is a piece of information the advertiser wants and cannot get on their own.
What AI Brand Visibility Means
AI brand visibility is the measure of whether, how often, and in what terms a brand appears inside the answers that AI assistants generate. It covers four things: whether the brand shows up at all when someone asks a question in its category, how prominently it is placed when it does, whether the appearance carries a link back to the brand or only names it, and what the surrounding text actually says about it. It is a measure of presence inside an answer, not a measure of traffic arriving from one.
That last distinction is what makes it unfamiliar. Every reporting habit publishers and advertisers built over twenty years assumes the value showed up as a visit. AI brand visibility describes value that lands entirely on somebody else’s surface and never files a record on yours.
Why the Question Became Answerable This Year
Two things had to be true before a publisher could sell anyone a straight answer here. The surface had to be large enough to matter, and the answers had to be observable.
Both are now true.
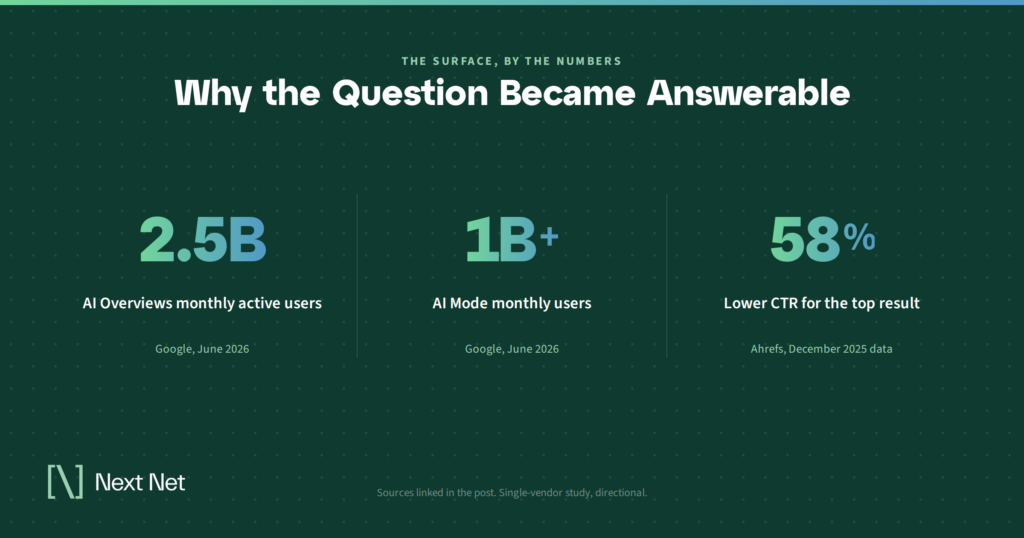
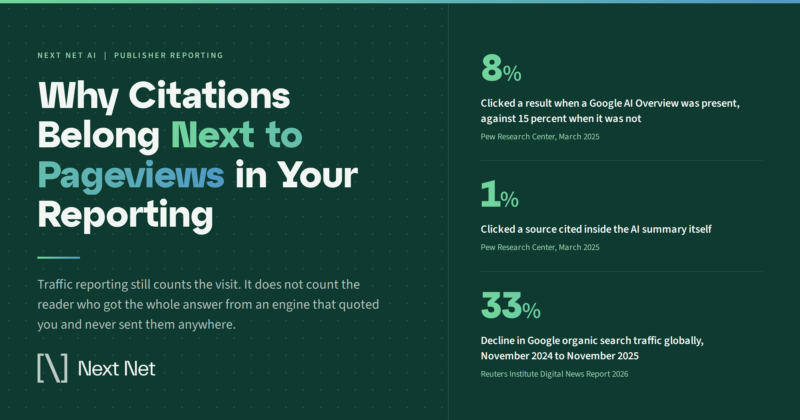
On the scale question, Google reported in June 2026 that AI Overviews had passed 2.5 billion monthly active users and AI Mode had passed one billion. That is not an emerging channel. That is the default front end of the largest discovery system your advertisers have ever bought against.
The cost side is measurable too. Ahrefs re-ran its click-through study using December 2025 data across 300,000 keywords and found that the presence of an AI Overview lines up with a 58 percent lower click-through rate for the top-ranking page, up from the 34.5 percent the same team measured a year earlier. Vendor research, single-source, and worth reading alongside the others, but the direction has been consistent across every study that has looked.
Observability is the newer half. AI answers are generated fresh, vary between runs, and leave no impression log on the brand’s side. But they can be sampled. Ask the questions a buyer would ask, across ChatGPT, Gemini, Perplexity, Copilot, and Google AI Overviews, record what comes back, and repeat on a cadence. That produces something you can read.
Which is where a publisher has an advantage nobody else in the chain has. You already know which questions matter in your category, because you have been answering them in your coverage for years.
Reading Share of Voice for an Advertiser
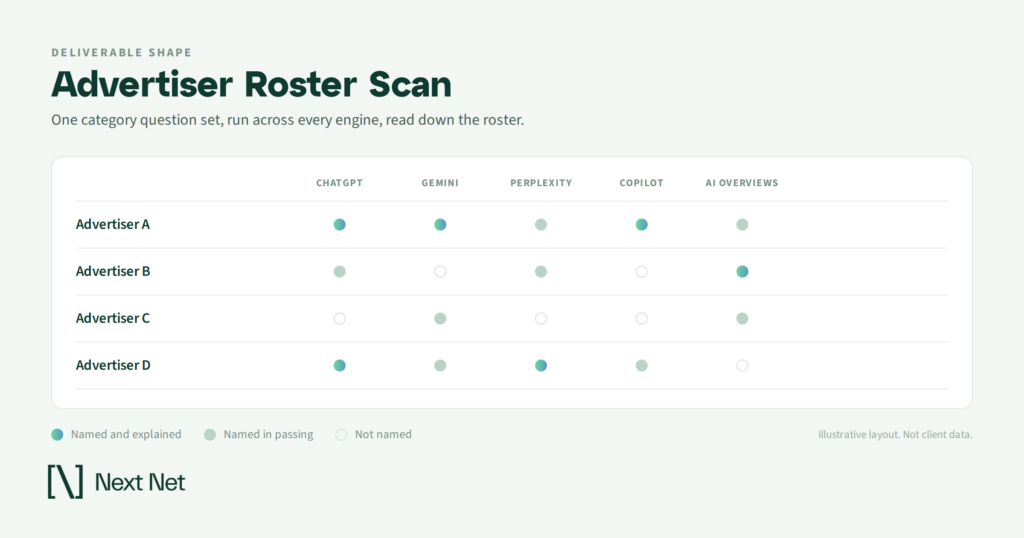
Share of voice is the first number worth pulling, and it answers the crudest version of the question: across the set of questions that define this category, how often does this brand come up at all.
Run thirty questions. Count the answers your advertiser is named in. That proportion is their share of voice, and on its own it means very little.
It becomes useful the moment you put a second brand next to it. A brand named in a third of category answers looks respectable until the rival nobody in the room takes seriously turns up in two thirds. Share of voice is a comparative instrument or it is decoration.
The composition matters more than the count. Look at which questions produce the appearances. A brand that shows up reliably on questions about its own name and almost never on questions about the category problem it solves has a specific, fixable issue: the engines know who it is and do not associate it with the thing people are actually asking about. That is a coverage gap, not a reputation gap, and the two get confused constantly.
Sort your questions into two piles before you count anything. Branded questions, the ones that contain the advertiser’s name, and unbranded questions, the ones a buyer asks when they do not yet know who to call. Almost every brand performs better on the first pile. The gap between the two piles is the read.
A brand strong on both is defending a position. A brand strong on branded and weak on unbranded is invisible at the exact moment a purchase decision is forming, which is the finding most likely to change what somebody does on Monday. A brand weak on both has a more basic problem and probably knows it already.
Our guide to where your brand appears and who appears with you goes deeper on reading the company a brand keeps inside an answer.
One caution before you show a number to anybody. Thirty questions is a sample, and a small one. Say “roughly a third” and say how many questions you asked. Do not say 34.2 percent. A decimal on a thin sample is the fastest way to have the entire read dismissed by the one person in the room who understands sampling.
Reading the Citation Footprint
Share of voice tells you the brand was in the room. It does not tell you whether being there did anything.
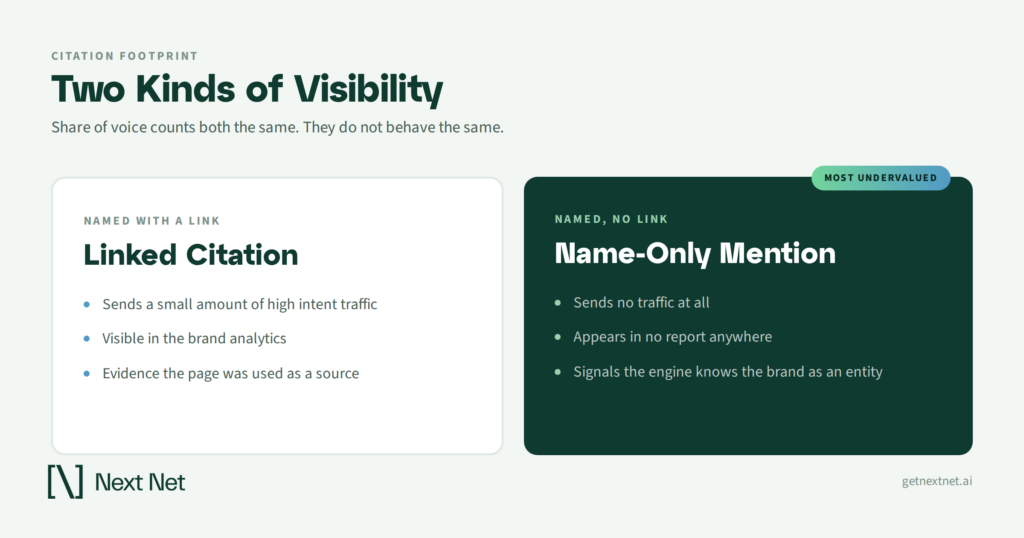
The citation footprint is the second read, and it separates two things that share of voice collapses together. When a brand appears, is it named with a link back to its own property, or named and nothing more? And is the answer built on the brand’s own material, or on somebody else’s account of it?
Both variants are real visibility and they behave completely differently.
A linked citation sends a small amount of extremely high-intent traffic and gives the brand something its analytics can see. A name-only mention sends nothing, shows up in no report, and is often the stronger signal, because it means the engine treats the brand as a known entity in the category rather than as a page it needed to source. The second kind is what brand equity looks like when a language model has it.
The distinction between what AI links to and what it merely mentions is worked through in detail in our citation footprint guide.
Here is the part that belongs to you rather than to the advertiser. When you run these questions, note which outlets the engines cite. If your titles are in that set, you have just documented something no rate card has ever been able to state: your coverage is part of the material these systems build category answers from. If your titles are absent from a category you cover heavily, that is a finding about your own visibility, and it is worth as much attention as anything you learned about the advertiser. Our guide on which sources AI trusts in your coverage area covers how to read that list.
The Three Reads That Tell You Something
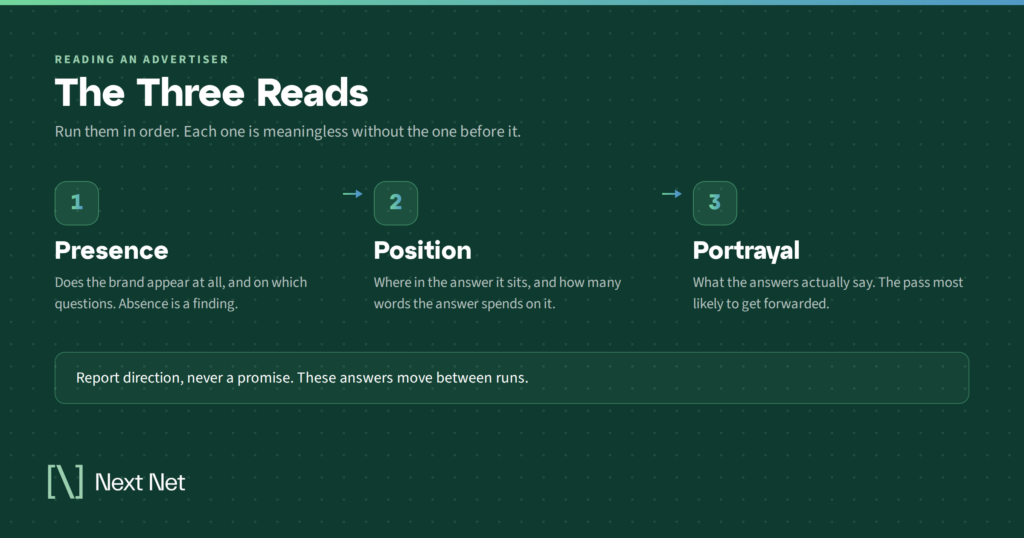
A useful read has three passes, and they go in this order because each one is meaningless without the one before it.
Presence. Does the brand appear, and on which questions. This is the pass that surfaces absence, and absence is the finding that gets skipped most often, because nothing on the advertiser’s side generates data when they are not mentioned. An answer still happened. Someone else supplied it.
Position. Where in the answer does the brand sit, and how much of the answer does it occupy. First name in a list of three behaves differently from seventh in a list of nine, in roughly the way position on a results page used to behave. A brand can hold a healthy share of voice and be last in every single answer.
Length is part of position and easy to record. A brand given a sentence and a brand given a clause are not having the same appearance, even though both count as one. Note how many words the answer spends on each brand it names, and the picture usually resolves fast: one or two names get explained and the rest get listed.
Portrayal. What do the answers actually say. This is the pass that stops the read from being a numbers exercise. If four engines out of five raise the same objection about an advertiser, unprompted, that objection has become part of what the category believes about them. That is worth more to a brand manager than any share figure, and it is the finding most likely to get forwarded internally.
Portrayal is also where publishers are most useful, because judging whether an answer is fair requires knowing the category. A platform can tell you the sentiment score. Somebody who covers the beat can tell you whether the engine is repeating a criticism that stopped being true two years ago.
Turning the Read Into a Conversation
The read is only half of it. What you do with it is a separate discipline, and mostly a commercial one. We have written about packaging AI visibility as something a publisher can actually sell elsewhere, and that post covers the deliverable, the cadence, and how to structure it so it survives procurement.
What belongs here is narrower: how to hand somebody a finding about their own brand without it landing badly.
Lead with the specific, not the framework. “Here is what came back when we asked the five engines which provider to use in your category, and here is where you were” opens a conversation. An explanation of what AI brand visibility is closes one, because the person across from you now has to decide whether to care about a concept before they have seen anything about themselves.
Bring the comparison. A finding about one brand in isolation is interesting. The same finding with a competitor’s result beside it is a meeting that runs long.
Say what you do not know. The sample size, the run date, which engines you covered, and the fact that these answers move between runs. Volunteering the limits is what separates a read somebody trusts from a report somebody checks.
Decide in advance who walks them through it. A document sent to a coordinator gets skimmed and filed. The same document presented by someone who can answer a follow-up question about the category turns into a conversation about next quarter. The interpretation is the part that has value, and interpretation does not survive being emailed.
And report direction, never a promise. These systems are probabilistic and they change without notice. You can tell an advertiser what the answers said in the week you asked. You cannot tell them what the answers will say next quarter, and the moment you imply otherwise, the whole thing becomes a claim you have to defend instead of a finding you can discuss.
Where This Gets Misread
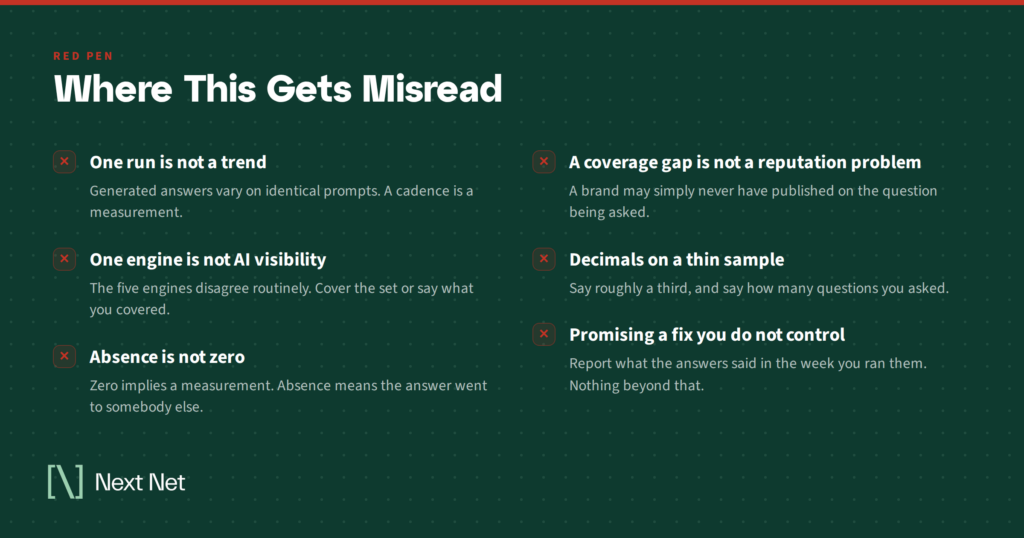
Treating one run as evidence. Generated answers vary on identical prompts. A single check is an anecdote. A repeated check on a fixed question set is a measurement.
Reading one engine and calling it AI visibility. ChatGPT, Gemini, Perplexity, Copilot, and Google AI Overviews disagree with each other routinely, and a brand that looks strong in one can be missing from another. Cover the set, or state plainly which part of the set you covered.
Reporting absence as zero. Zero implies a measurement was taken and came back empty. Absence usually means the answer went to somebody else, and naming who is the useful half.
Confusing a coverage gap with a reputation problem. A brand missing from category answers may have nothing wrong with its reputation. It may simply have never published anything on the question being asked. These get different remedies, and the wrong remedy wastes a quarter.
Letting the read go stale. These answers move week to week. A read taken in one quarter and presented in the next has a credibility problem the moment somebody in the room opens a chat window and checks.
Promising a fix you do not control. The honest position is that the underlying work is familiar. Google’s own guidance on optimizing for generative AI search states that from Google Search’s perspective this is still SEO, and that no special files or markup are required. What earns citations is largely what earned rankings: clear structure, a real answer near the top, and content worth drawing on.
Frequently Asked Questions
What is AI brand visibility?
AI brand visibility is whether, how often, and in what terms a brand appears inside AI-generated answers. It has four components: presence, prominence within the answer, whether the appearance is linked or name-only, and what the surrounding text says about the brand. It measures appearance on the engine’s surface rather than traffic arriving on the brand’s own.
How do you measure a brand’s visibility in AI answers?
By sampling. Fix a set of questions a buyer in the category would actually ask, run them across ChatGPT, Gemini, Perplexity, Copilot, and Google AI Overviews, and record which brands appear, where in the answer, with or without a link, and what is said about them. Repeat on a cadence so movement between runs means something. Disclose the sample size, the engines covered, and the run date every time.
Why would a publisher measure this instead of the advertiser?
Because the two hardest parts are category knowledge and trust, and a publisher has both. Knowing which thirty questions matter in a vertical is editorial judgment. Knowing whether an engine’s criticism of a brand is fair requires covering the beat. And a finding delivered inside an existing relationship lands as help rather than as a pitch.
Is a name-only mention worth anything if it sends no traffic?
Yes, and it is routinely undervalued for exactly that reason. A mention without a link means the engine treats the brand as a known entity in the category rather than as a page it had to look something up in. It generates no analytics record, which is why it goes unreported, and it is a clearer signal of category standing than a linked citation is.
The Question Worth Bringing to the Next Meeting
The advertiser conversation has spent two years being a conversation about decline. Impressions, referrals, reach, all of it explained in the past tense.
This one is not that. It is a question your advertisers do not have an answer to, about a surface they cannot buy their way into, in a category you know better than the agency does. Appearing in an answer is a fact you can count. Being chosen inside one is a verdict, and the verdict is the part your advertiser has never seen.
Start with one vertical. Write down the questions a buyer asks before they choose. Run them, and look at who comes back.
If you want to see the shape of that deliverable before you build one, start with a Report Card for a brand in your category, or read more about how we work with publishers and partners.
Related Articles
Your monthly traffic report is still accurate. It has just stopped describing your audience. Sessions are down and search referrals…


Somewhere in your organization, a browser tab is open to a CDN bot settings page, and someone is hovering over…
The revenue meeting has a new column in it. Not a bigger one. A new one. For most publishers, the…